 Instruction and application
 In Progress
Model calibration - Is your model confident for the right reasons?
** Your model says there's a 90% chance a loan will default.**
Should you believe it?**
In many real-world applications, it's not just the prediction that matters—it's the confidence behind it. Especially in high-stakes environments like healthcare, finance, or security, miscalibrated probabilities can lead to overconfidence and loss of trust.
Example
Imagine your loan default model assigns a 95% risk score to some borrowers—but in reality, only 80% default. At the other end, borrowers scored at 10% still default 25% of the time.
The model’s predictions are off—** overconfident at the top, underconfident at the bottom** . That’s a calibration problem, not an accuracy issue.
Platt scaling: Quick and smooth recalibration
When your model’s probability scores are mostly accurate but consistently a bit off—Platt scaling can help you fix them fast. It’s a lightweight calibration method that applies logistic regression to your model’s outputs, adjusting them to better match reality.
Platt scaling works by fitting a ** sigmoid function**—a smooth, S-shaped curve—to your model’s raw outputs. This adjusts the scores to better reflect how often events actually occur.
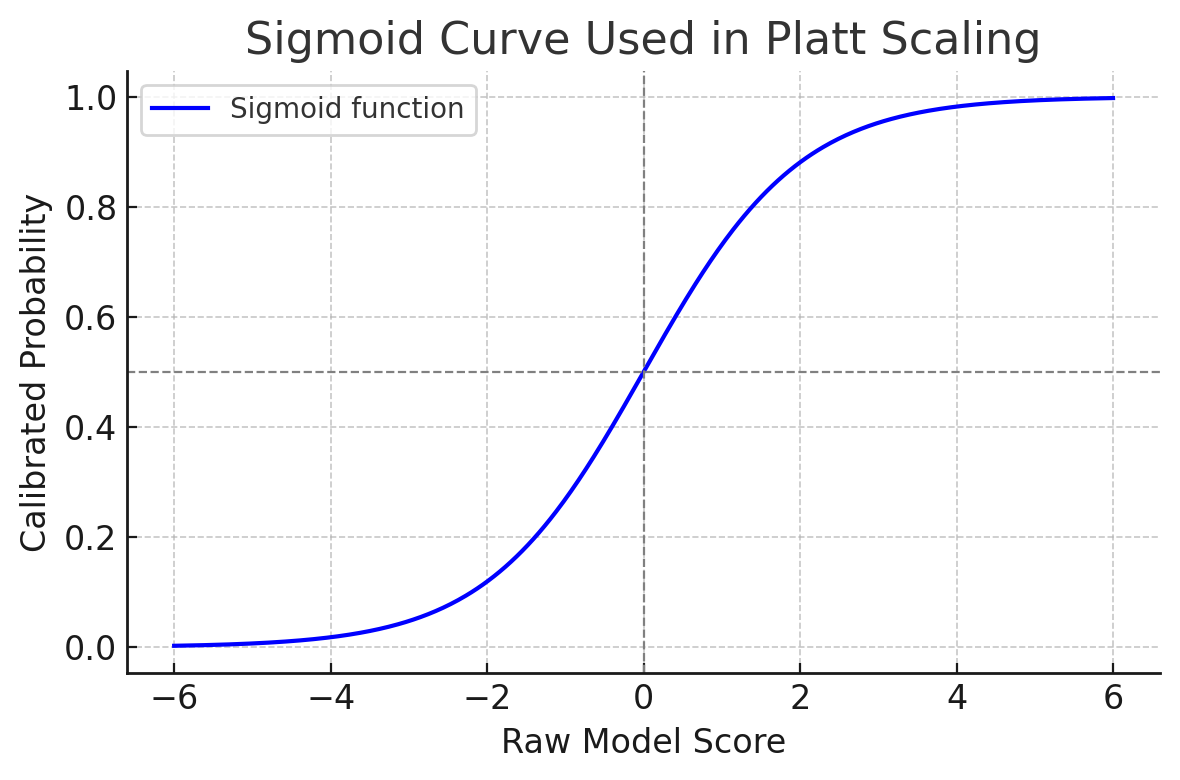
How Platt scaling works
Here’s how the sigmoid function is applied:
-
Collect raw model scores and true labels from a validation set.
-
Fit a sigmoid function using the raw scores as input and actual labels as output.
-
Apply the fitted sigmoid to future raw model scores to generate calibrated probabilities. This process does not change the underlying model—it simply layers a calibration step on top. The sigmoid function transforms the raw scores, smoothing out overconfident predictions and boosting underconfident ones—especially in the mid-range where models often struggle.** When to use Platt it:**
-
You need a ** fast, lightweight** calibration method.
-
Your model’s miscalibration is ** smooth and systematic** .
-
You’re working with a ** moderate-sized dataset** suitable for fitting a simple regression.
Example: Fraud detection model
You’ve deployed a fraud detection model that outputs risk scores for incoming transactions. During testing, it looked solid—but in production, something feels off.
Your analysts notice the model ** predicts 0.9 confidence** for dozens of cases—yet only** 70% of those are actually fraudulent** . That’s a problem. With so many false alarms, trust in the model drops, and the team starts ignoring alerts or spending hours chasing non-issues.
Instead of retraining the model, you apply ** Platt scaling** to recalibrate the risk scores. The sigmoid correction** lowers inflated probabilities** while preserving the ranking of risk.
Now, a 0.9 score more accurately reflects the ** true likelihood of fraud** , helping your analysts focus on the right cases—and restoring confidence in the system.
Isotonic regression: Flexible calibration when precision matters
Not all miscalibration follows a smooth curve. Sometimes your model’s predicted scores are off in inconsistent, jagged ways. That’s when ** Isotonic Regression** becomes valuable—it adapts to your data without assuming a specific shape like Platt scaling does.** Isotonic Regression** is a non-parametric technique that fits a** monotonic step-wise function** to your model’s scores. That means:
-
The calibrated probabilities always increase as the raw scores increase.
-
But the steps can be irregular—giving the method flexibility to correct ** non-linear distortions** . This makes it especially useful when:
-
Your model shows erratic overconfidence in one range and underconfidence in another.
-
You need ** precise score-to-outcome mapping** across multiple probability bands.** When to use it:**
-
You have ** enough data** to support a more flexible calibration.
-
Calibration errors are ** non-linear or scattered** .
-
You need ** fine-tuned reliability** across all decision thresholds (e.g., in healthcare or credit scoring).** Example: Medical triage model**
You’re developing a model to predict the likelihood that patients need urgent care. Their scores determine triage priority:
- Patients with scores ** above 0.7** are seen immediately.
0.4 to 0.7
monitored.
Below 0.4
asked to wait.
But after deployment, you find the model behaves erratically:
- Some patients with 0.3 scores later escalate—too risky to ignore.
- Others with 0.7 scores turn out fine—too many false alarms. The calibration is inconsistent. You try Platt scaling, but its sigmoid shape can’t correct these nonlinear issues. So you apply ** Isotonic Regression** , which fits a** step-wise correction** that better reflects observed risk.
Now, each probability band maps more accurately to clinical need—improving both safety and resource use.
Comparing Platt and Isotonic calibration
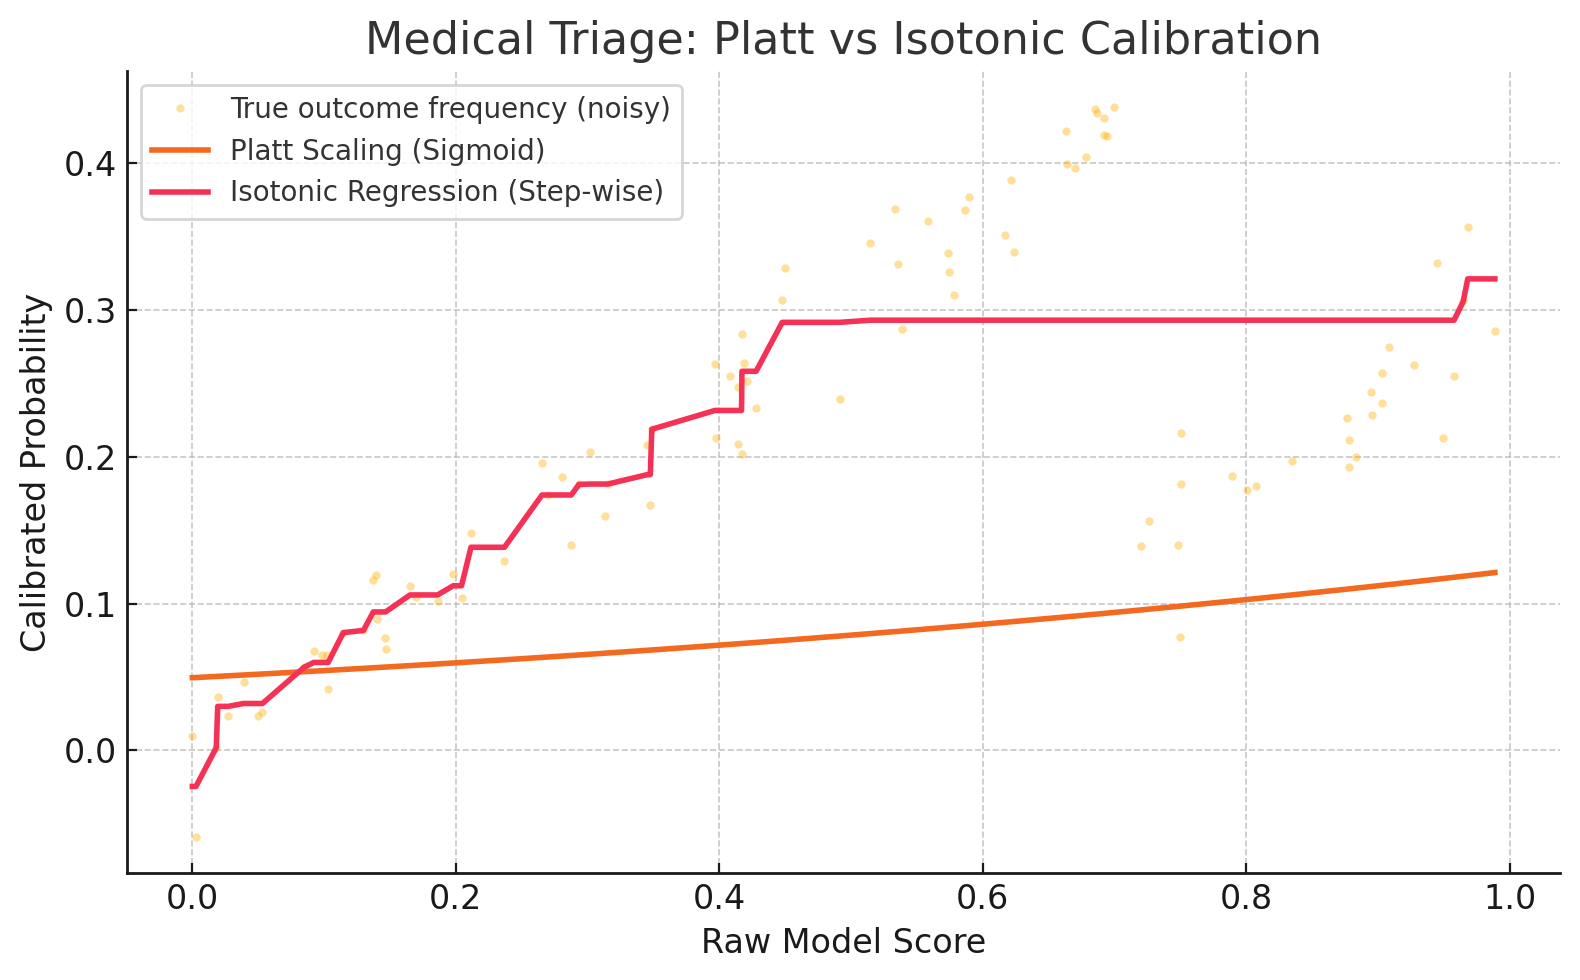
In the following graph, you can see how the two methods differ when applied to the same model:
Dots
represent observed outcomes.
Blue line
Platt scaling (smooth sigmoid).
Orange line
Isotonic regression (step-wise fit).
The Isotonic method captures mid-range irregularities more precisely—perfect for high-stakes predictions like patient triage.
 ** Calibration vs. complexity: Choosing the right trade-off**
Confidence calibration improves trust—but it’s not free. Each method adds computational cost, especially at inference time.
When working in resource-constrained or latency-sensitive environments, it’s important to choose a method that balances accuracy with practicality.
Select the tabs to learn more:** Use lighter-weight methods (like Platt scaling) when:**
-
You’re deploying on ** mobile apps, edge devices, or embedded systems** .
-
Even ** small prediction delays** could impact user experience (e.g., in real-time fraud detection).
-
Your model is already well-calibrated and only needs ** mild corrections** .** Use more flexible methods (like Isotonic regression) when:**
-
You’re operating in ** batch or offline settings** where latency is less critical.
-
You need ** high-granularity probability accuracy**—as in healthcare triage or credit underwriting.
-
Poor calibration could lead to ** costly or high-risk decisions** , not just reduced precision.
Key takeaway
Calibration isn't just about correctness—it’s also about ** fit-for-purpose deployment** . The best method is the one that balances trust, accuracy, and efficiency in your specific context.
Action item: Mini scenario reflection ** Scenario:** You’re deploying a machine learning model that prioritises patients for follow-up testing based on cancer risk scores.
Consider the following questions.